
How AI Is Changing Game Preservation.
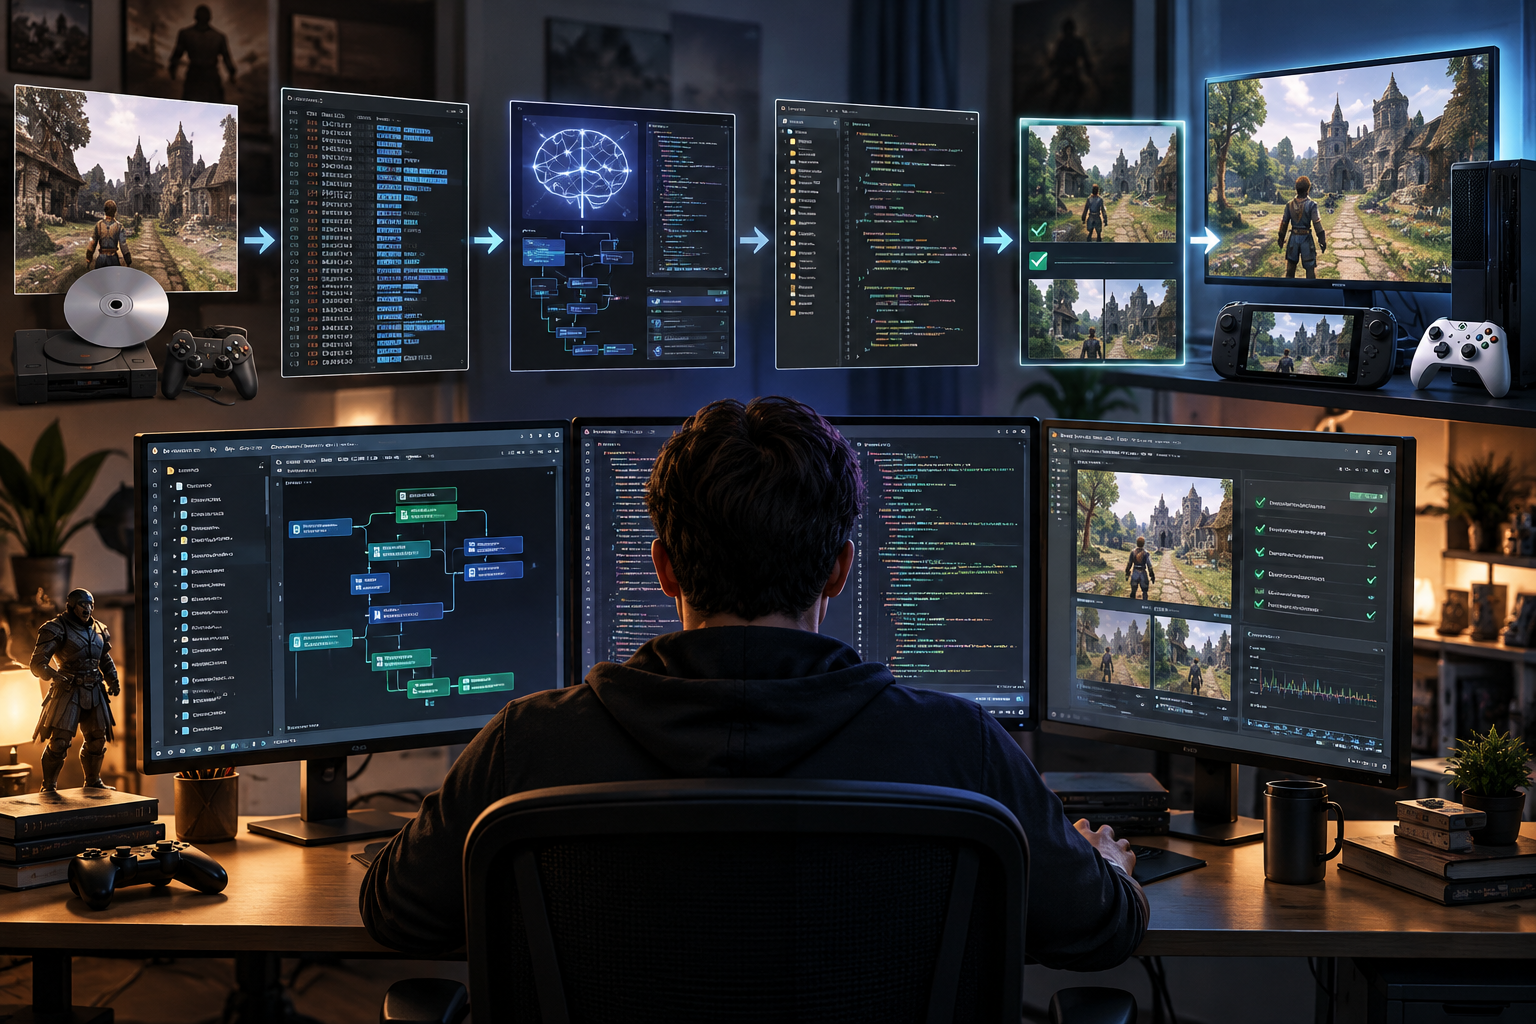
The shape of a modern recomp project for a game
A decompilation project starts with a compiled game, usually an executable or a set of platform-specific binaries. The goal is to recover source code that behaves like the original program. A recompilation project takes that recovered code and adapts it to a new compiler, operating system, or hardware target.
The distinction is useful, although real projects often combine both activities. Recovered code may need platform abstractions, replacement libraries, input changes, graphics work, and build-system changes before it can produce a usable port.
This work has become more visible as projects have moved from isolated reverse engineering efforts to public, trackable repositories. Chances are if you google a pre 2010s video game and add a recomp/decomp right next to the search text, the game already has a repository for it available on GitHub. There are sites like https://recomp.fyi/ which lets you know about the statuses of a given game in a more concise manner, however as the site gets its data from scrapers and people putting up their projects, some of the projects aren't versed well. Together, these resources make it easier to see which games have active efforts, where the code lives, and how far a project has progressed.
What is the actual difference between a recompilation and a decompilation project?
A decomp is an effort to manually reverse engineer a game's binary back into clean source code until it 1:1 matches the original output. It is painfully slow, but it yields human-readable C/C++ code, making it the closest you can get to the original project without the developers releasing the source code itself.
Recompilation is an automated translation process using tools like N64 Recompiled or ReXGlue. Instead of recreating human-readable source code, these tools automatically convert the original binary instructions into code that can be compiled for modern platforms. The resulting code isn't clean or easy for humans to read, but it allows games to run natively on new systems in a fraction of the time.
Both of these explanations are on the high level as neither a decompilation process is a fully manual task and neither is a recompilation fully automated. The key difference with AI results in both of these type of projects getting done significantly faster. Decomps could take years previously even when a team of high skilled individuals worked on them and recompilation still requires significant manual intervention for edge cases, memory management, and hardware hooks.
How do people start with a recomp/decomp?
Before writing anything, establish what already exists.
A useful first pass should answer a few practical questions:
- Is the project focused on decompilation, recompilation, or a source port?
- Which version of the game is being targeted?
- Are the original binaries required to build or test it?
- What platforms and toolchains are supported?
- Does the repository contain recovered source, generated code, patches, or only research notes?
- Are there legal or distribution limits around the original game data?
The repository for Fable 2 Recomp is an example of the kind of project developers can inspect directly. A repository gives more useful evidence than a project name alone: build instructions, source layout, dependencies, open issues, and the boundary between code that has been recovered and code that still needs work.
What AI helps with
AI coding tools are useful when the project has a large amount of repetitive or partially understood code. They can help a developer:
- Rename functions and variables consistently after their purpose is understood.
- Convert decompiler output into readable C or C++.
- Explain control flow in a small function.
- Generate wrappers around platform APIs.
- Fill in repetitive declarations and build files.
- Search a repository for related functions, constants, and data structures.
- Suggest tests for a recovered subsystem.
The useful unit of work is usually small. Give the tool one function, one call path, or one platform boundary. Include the known calling convention, argument types, nearby declarations, and any observed behavior. Then review the result against the binary and the program's runtime behavior.
AI can produce plausible code when the available information is incomplete. That is a problem in reverse engineering because plausible code can compile while still changing the original behavior. A generated name can also spread a wrong assumption through dozens of later changes.
For that reason, AI output works best as a draft for a human who already has evidence. The tool can reduce typing and help compare alternatives. It cannot establish that a recovered function has the right side effects, memory layout, or timing.
Map behavior before cleaning up code
A reliable workflow separates identification from refactoring.
First, preserve the raw evidence. Keep the original function address, binary version, decompiler output, and any notes about calls or data references. Record which conclusions are confirmed and which are guesses.
Next, map the surrounding behavior. A function that appears to update a value may also set a flag, write to a global object, or trigger a callback. Its name should reflect what the evidence supports, rather than what the first decompiler view suggests.
Only then should the code be made easier to read. Rename symbols, introduce structures, split large functions, and replace platform-specific code with a clear interface. Each change should remain easy to compare with the original behavior.
This approach also gives AI tools better context. A prompt containing a known structure layout and a short call graph is more useful than a prompt containing an unexplained block of decompiled code.
Recompilation adds a second engineering problem
Matching the original binary is only part of the task. A recompilation project must also produce code that can build and run in a new environment.
Common boundaries include:
- Graphics and windowing APIs.
- Audio and input systems.
- File paths and asset loading.
- Threads, timers, and synchronization.
- Compiler-specific types and calling conventions.
- Memory allocation and alignment.
- Build tools and third-party libraries.
These boundaries should be isolated behind small interfaces where possible. Keeping platform code in a few clearly marked areas makes later ports easier and gives tests a stable place to run.
The original game may also depend on behavior that was never documented. Differences in floating-point operations, integer sizes, structure packing, filesystem behavior, or thread scheduling can appear as visual bugs or crashes far away from the real cause.
What public project trackers contribute
A project directory does more than collect links. It gives contributors a shared vocabulary for describing project status and scope. Developers can distinguish a research repository from a buildable recompilation, or a full port from a partial subsystem.
That visibility helps with project selection. Someone interested in graphics can find a project with an active renderer layer. Someone studying reverse engineering can choose a repository with documented analysis. Someone looking for a way to contribute without reversing a binary can work on build tooling, tests, documentation, or platform support.
The same visibility also makes unfinished work easier to understand. A public board should be read as a map of ongoing efforts, not as proof that every listed project is complete or directly buildable.
Lessons for developers using AI coding tools
Treat the binary and runtime behavior as the source of truth. Treat decompiler output and AI suggestions as working material.
Give AI tools narrow tasks with explicit evidence. Ask for explanations and alternative interpretations before asking for a large rewrite. Keep generated changes separate from confirmed analysis so a mistaken assumption does not become difficult to remove.
Use the tool for repetition, search, scaffolding, and code cleanup. Keep decisions about function identity, data layout, ownership, platform behavior, and correctness under human review.
Projects listed by Recomp.FYI show how much easier discovery becomes when this work is public. Repositories such as Fable 2 Recomp show the other side of the process, where the interesting questions are visible in source, build instructions, and the remaining gaps. The result is a more practical path from an old binary to code that developers can inspect, test, build, and adapt.
Sources:
https://www.reddit.com/r/decomps/
https://recomp.fyi/
https://github.com/himdo/Fable-2-Recomp